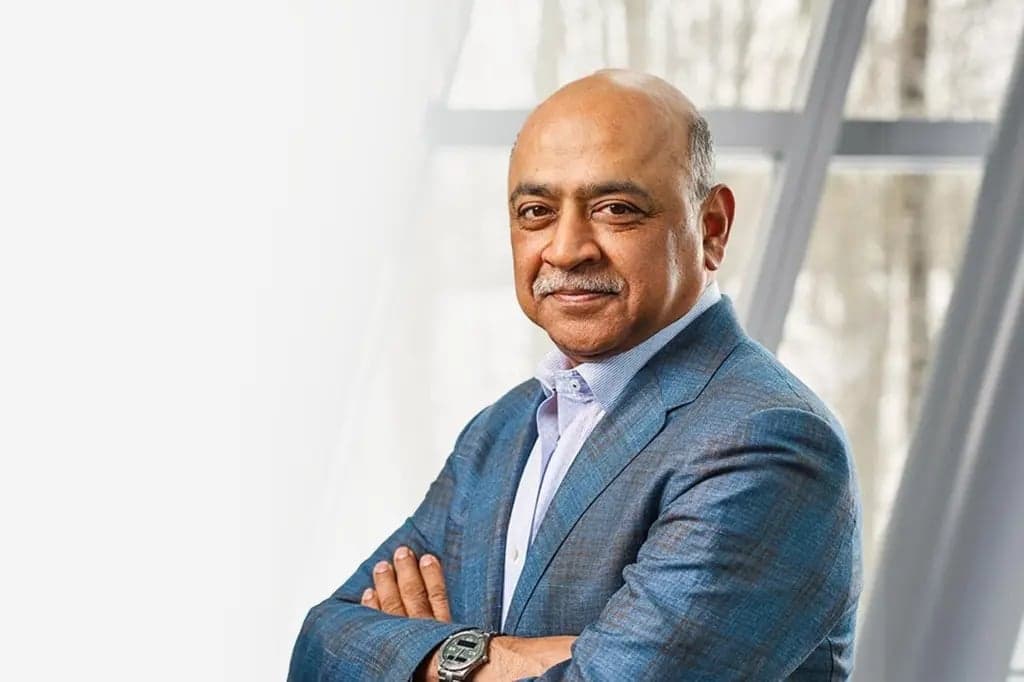
IBM chairman, president, and chief executive Arvind Krishna has argued that companies responding to rising AI costs by rationing token usage are making a mistake that will cost them competitively over time. In his view, capping how much employees can use AI models is a slow way to lose, since it treats AI as an expense to be contained rather than a capability to be made more efficient.
Krishna's criticism is aimed at a defensive pattern he sees spreading across large companies: spending caps on AI usage, hard limits on the number of tokens employees can consume, and restricting the most capable models to a narrow group of approved users, all driven by concern over how expensive running these systems has become in production.
His alternative is to attack the cost structure itself rather than access to it. Krishna points out that AI agents typically read around 600 words for every word they actually generate, and that most of that reading is repetitive, the same context and data processed again and again. Caching, which keeps previously processed data available instead of reprocessing it from scratch, is one fix IBM has used internally, and Krishna says it allowed IBM's own systems to handle seven times more work on the same hardware.